
Published measures
Reasoning ruler, error bar at each level
| Level | Standard error | Judgments |
|---|---|---|
| Level 8 (Concrete) | ± 0.070 | 342 |
| Level 9 (Abstract) | ± 0.056 | 230 |
| Level 10 (Pre-Formal / Abstract-Formal transition) | ± 0.056 | 230 |
| Level 11 (Formal) | ± 0.032 | 232 |
| Level 12 (Systematic) | ± 0.019 | 225 |
No total row. Gate passed 2026-08-22. Unit: one level of the ruler.
Trace
Each row resolves to its question IDs, their answer keys and the bank fingerprint, in the dated report of the certifying run.
Every published result, with its date.
The ruler's error bar at each level. Each judge's ceiling, with its pass counts. Never a bare rank.
The precision we publish.
Measured on the reasoning ruler. Standard error 0.07 of a level or better at levels 8 to 12, gate passed 2026-08-22. Newer scales must clear 0.10 at each level, and 0.15 at level 1.
Has the ruler moved?
The question set is frozen, fingerprinted and dated. Every run checks the fingerprint first. Whether the ruler holds steady over months is the next exhibit, and it is not done yet.
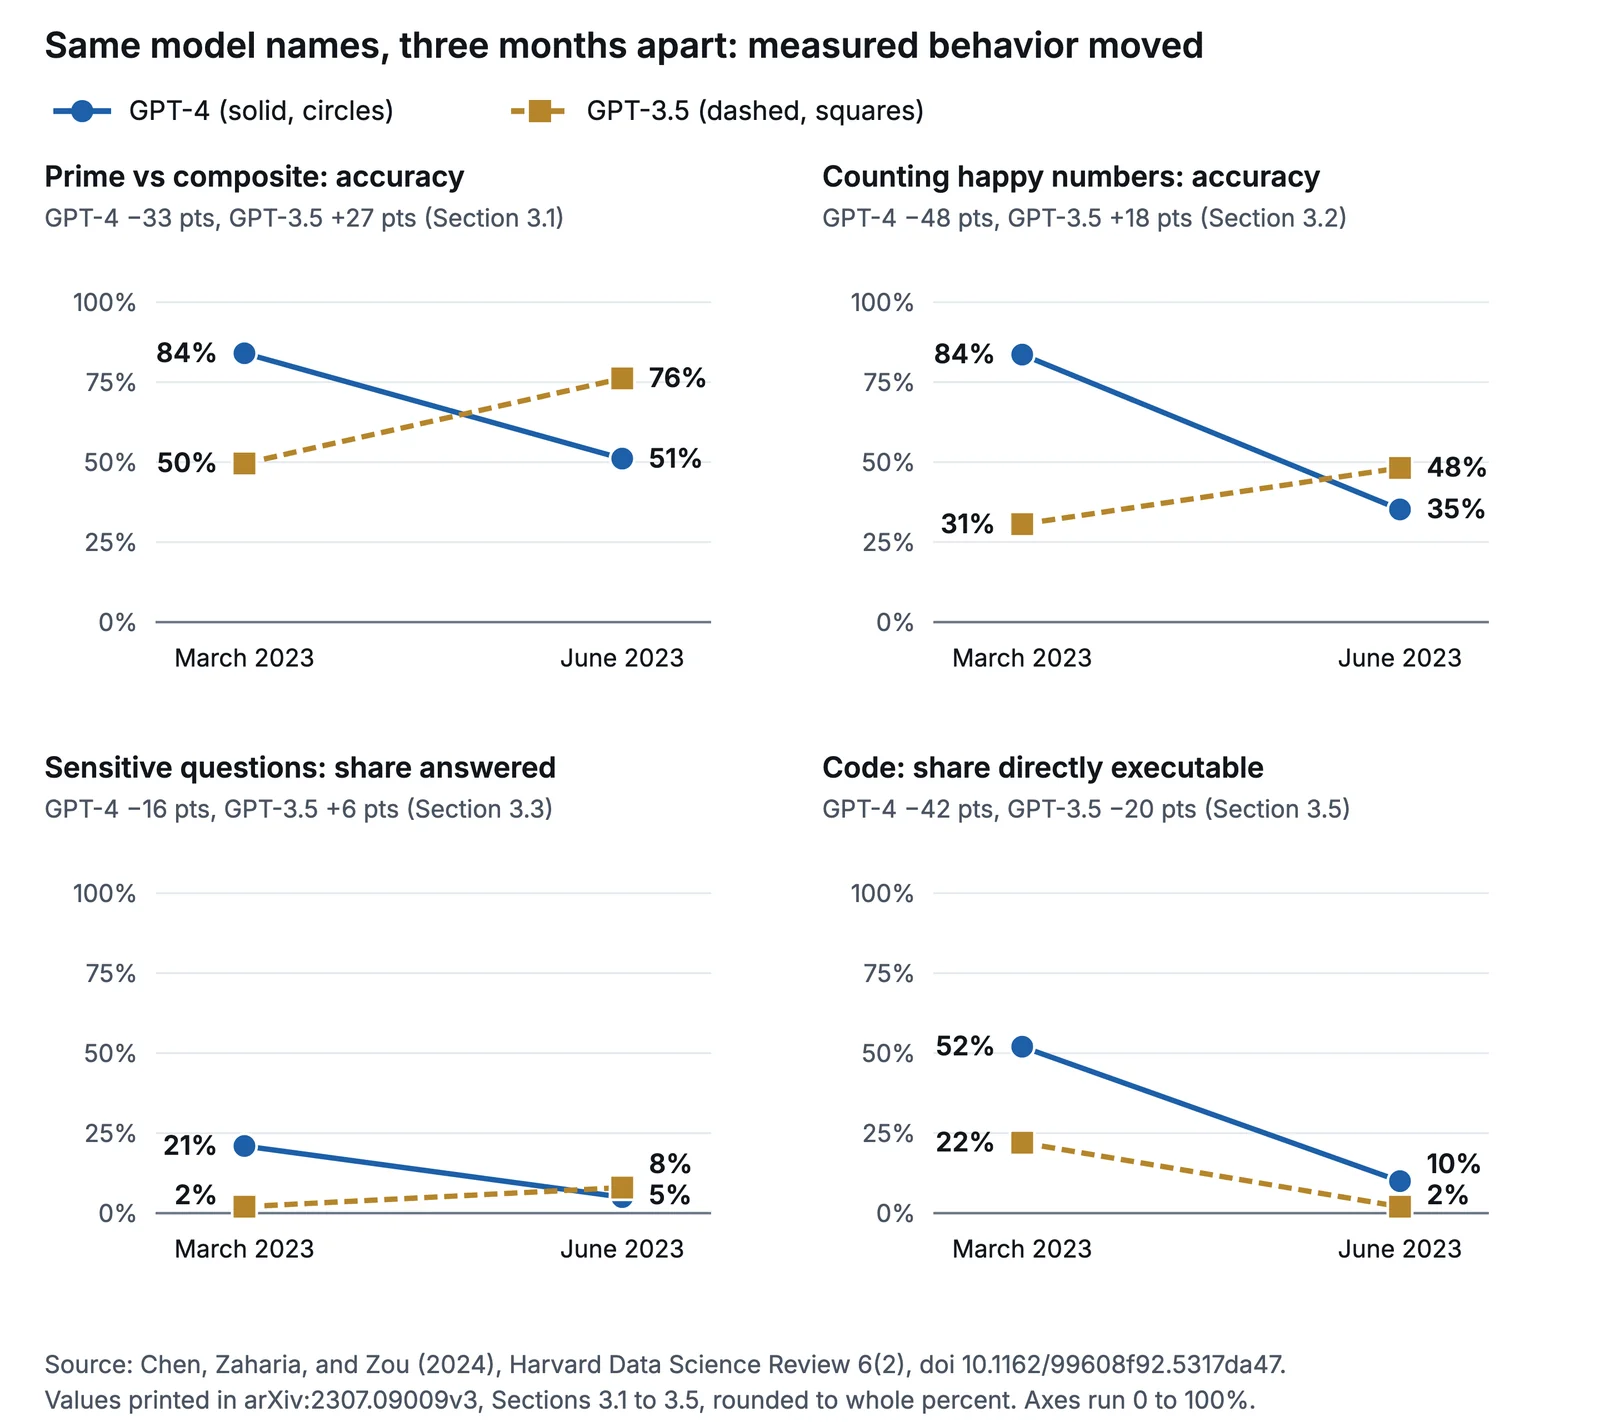
Elsewhere, models have moved. Same model names, three months apart, gave different results.
Our re-measurement: not yet shown.
Re-measurement run: not yet published.
Is the ruler circular?
Each level is fixed before any answer is graded. Three more guards keep the ruler from grading itself.
Levels 7 to 9: a certified set of 12 judges, from different vendors and countries, reads the same texts. Each judge is checked against the others. The credentialing run is in progress, with no results yet.
Levels 10 to 13: the questions are new. One company writes them. A different company attacks them. Neither judges them. The questions stay sealed and unpublished until the judges read them. The judges for these levels are candidates, still being screened.
So the levels are set first. The questions are unseen. And for the new questions, the writer, the attacker and the judges work for separate companies.
A check against outside human experts: still ahead.
Judges, levels 7 to 9
In the certified set. Credentialing run in progress, no results yet.
- Gemma 4 31B Google
- Gemma 4 26B Google
- Gemma 3 27B Google
- GPT-6 Luna
 OpenAI
- GPT-OSS 120B OpenAI
- Mercury 2.5 Inception
- Mistral Small 3.2
 Mistral
- Nemotron 3 Nano 30B NVIDIA
- MiMo V2.5 Xiaomi
- Qwen 3 8 Flash Alibaba level 8 only
- Qwen3 235B Alibaba level 8 only
- Jev TypeSafe
Write and attack the questions
- Writes and repairs the questions

 Anthropic
- Attacks the questions
 xAI if it passes a reliability check; Anthropic as fallback
Judges, levels 10 to 13
Candidates being screened. Not a final roster.
- A subset of the level 7 to 9 judges levels 10 to 12
- DeepSeek V4.1 Flash DeepSeek levels 10 to 13
- GLM 5.3 Flash Z.ai levels 10 to 12
- Kimi K3
 Moonshot level 12 and up
- GPT-6 Astra OpenAI level 13, one-level trial first
Roster as of 2026-10-02. No Anthropic model judges at any level. No xAI model judges at levels 10 to 13. Flags show each vendor's home country.
Vendor and model names are used only to identify the models XLNC measures. XLNC is not affiliated with, sponsored by, or endorsed by these companies, and their inclusion does not imply their approval of any result. All names belong to their respective owners.
The board.
Two judge ceilings are published. Both sit at level 11, with a stated condition. Ceiling rule met
Neither of these judges is in the current roster. The record stays here, with its date. The current roster is on the Judges page.
A ceiling is a pass or fail result at each level, so each row shows its pass counts and its date.
The bottom of the range is not mapped yet. The board is regenerated after the next judge runs.
| Judge | Ceiling level | Passes | Condition | Measured | Status |
|---|---|---|---|---|---|
| z-ai-glm-5-3 z.ai | 11 | Break at level 12: 5 of 7. | Passes above the break do not count. | 2026-08-19 | Not in the current judge roster. Record kept. |
| deepseek-v4-flash-0731 DeepSeek | 11 | Break at level 12: 4 of 7. | Passes above the break do not count. | 2026-08-19 | Stale since 2026-09-20: the maker released a new version. Not in the current judge roster. Record kept. |
Harsh here, lenient there.
Jev1 sign change beyond the band
openai-gpt-oss-120b1 sign change beyond the band
qwen3-235b-a22b-instruct-2507no sign change beyond the band
deepseek-v4-1-flashno sign change beyond the band
kimi-k3no sign change beyond the band
Above 0 = harsher. Below 0 = more lenient. Pattern only; the exact values stay in the dated report. Shaded band: plus or minus 2 standard errors. Solid dot: admitted at that level; hollow: not admitted. A ring marks a sign change that clears the band on both sides. Level along the bottom. Judge registry of record b5ecea0af663, credential vintages 2026-09-20 and 2026-09-23.
The bend a raw score cannot see.
In a simulation on our own judge telemetry, a run set to a standard error of 0.20 came in at 1.16 with judge harshness left in. With it corrected, 0.21.1
Simulation.
- Gate passed 2026-08-22. Criterion met: a standard error at or below 0.07 of a level, with at least 30 judgments, at every level from 8 to 12.
- Ceiling rule met. Criterion: a judge's ceiling is the highest level it passes before a break; passes above a break do not count. Certifying runs: the reasoning-ceiling probe runs of 2026-08-19 and 2026-08-22, audited by our quality gate.
- The simulation used 15,000 judge decisions, dated 2026-09-09. Method and results are in the whitepaper. Whitepaper